
A2-Edit: Precise Reference-Guided Image Editing of Arbitrary Objects and Ambiguous Masks
Reference-guided object editing across categories, using only a coarse mask.
European Conference on Computer Vision (ECCV) 2026
Video generation & visual editing.
I’m a Ph.D. student at Shanghai Jiao Tong University, advised by Prof. Xiaohong Liu, and jointly trained at Shanghai Innovation Institute.
My research focuses on AIGC, especially video generation, video editing, and multimodal generation.

10 updates Scroll
Submitted 4 papers to AAAI 2027. Wish us luck!
Accepted A2-Edit at ECCV 2026.
Accepted SceneVLP in TCSVT.
Submitted 2 papers to NeurIPS 2026. Wish us luck!
Accepted LayerT2V at ICML 2026.
Released A2-Edit for reference-guided image restoration and editing. Submitted to ECCV 2026.
Released LayerT2V for multi-layer video generation, with a large-scale layered video dataset. Submitted to ICML 2026.
Accepted FlowDirector at CVPR 2026.
Released FlowDirector for training- and inversion-free video editing. Submitted to CVPR 2026.
Submitted 1 paper to TCSVT.
2026.09 — Present
Ph.D. · Computer Science and Technology
2026.09 — Present
Jointly Trained Ph.D. Student
2022.09 — 2026.06
B.Eng. · Software Engineering
Reference-guided object editing across categories, using only a coarse mask.
European Conference on Computer Vision (ECCV) 2026

Generates full videos, foregrounds, backgrounds, and alpha mattes together.
International Conference on Machine Learning (ICML) 2026
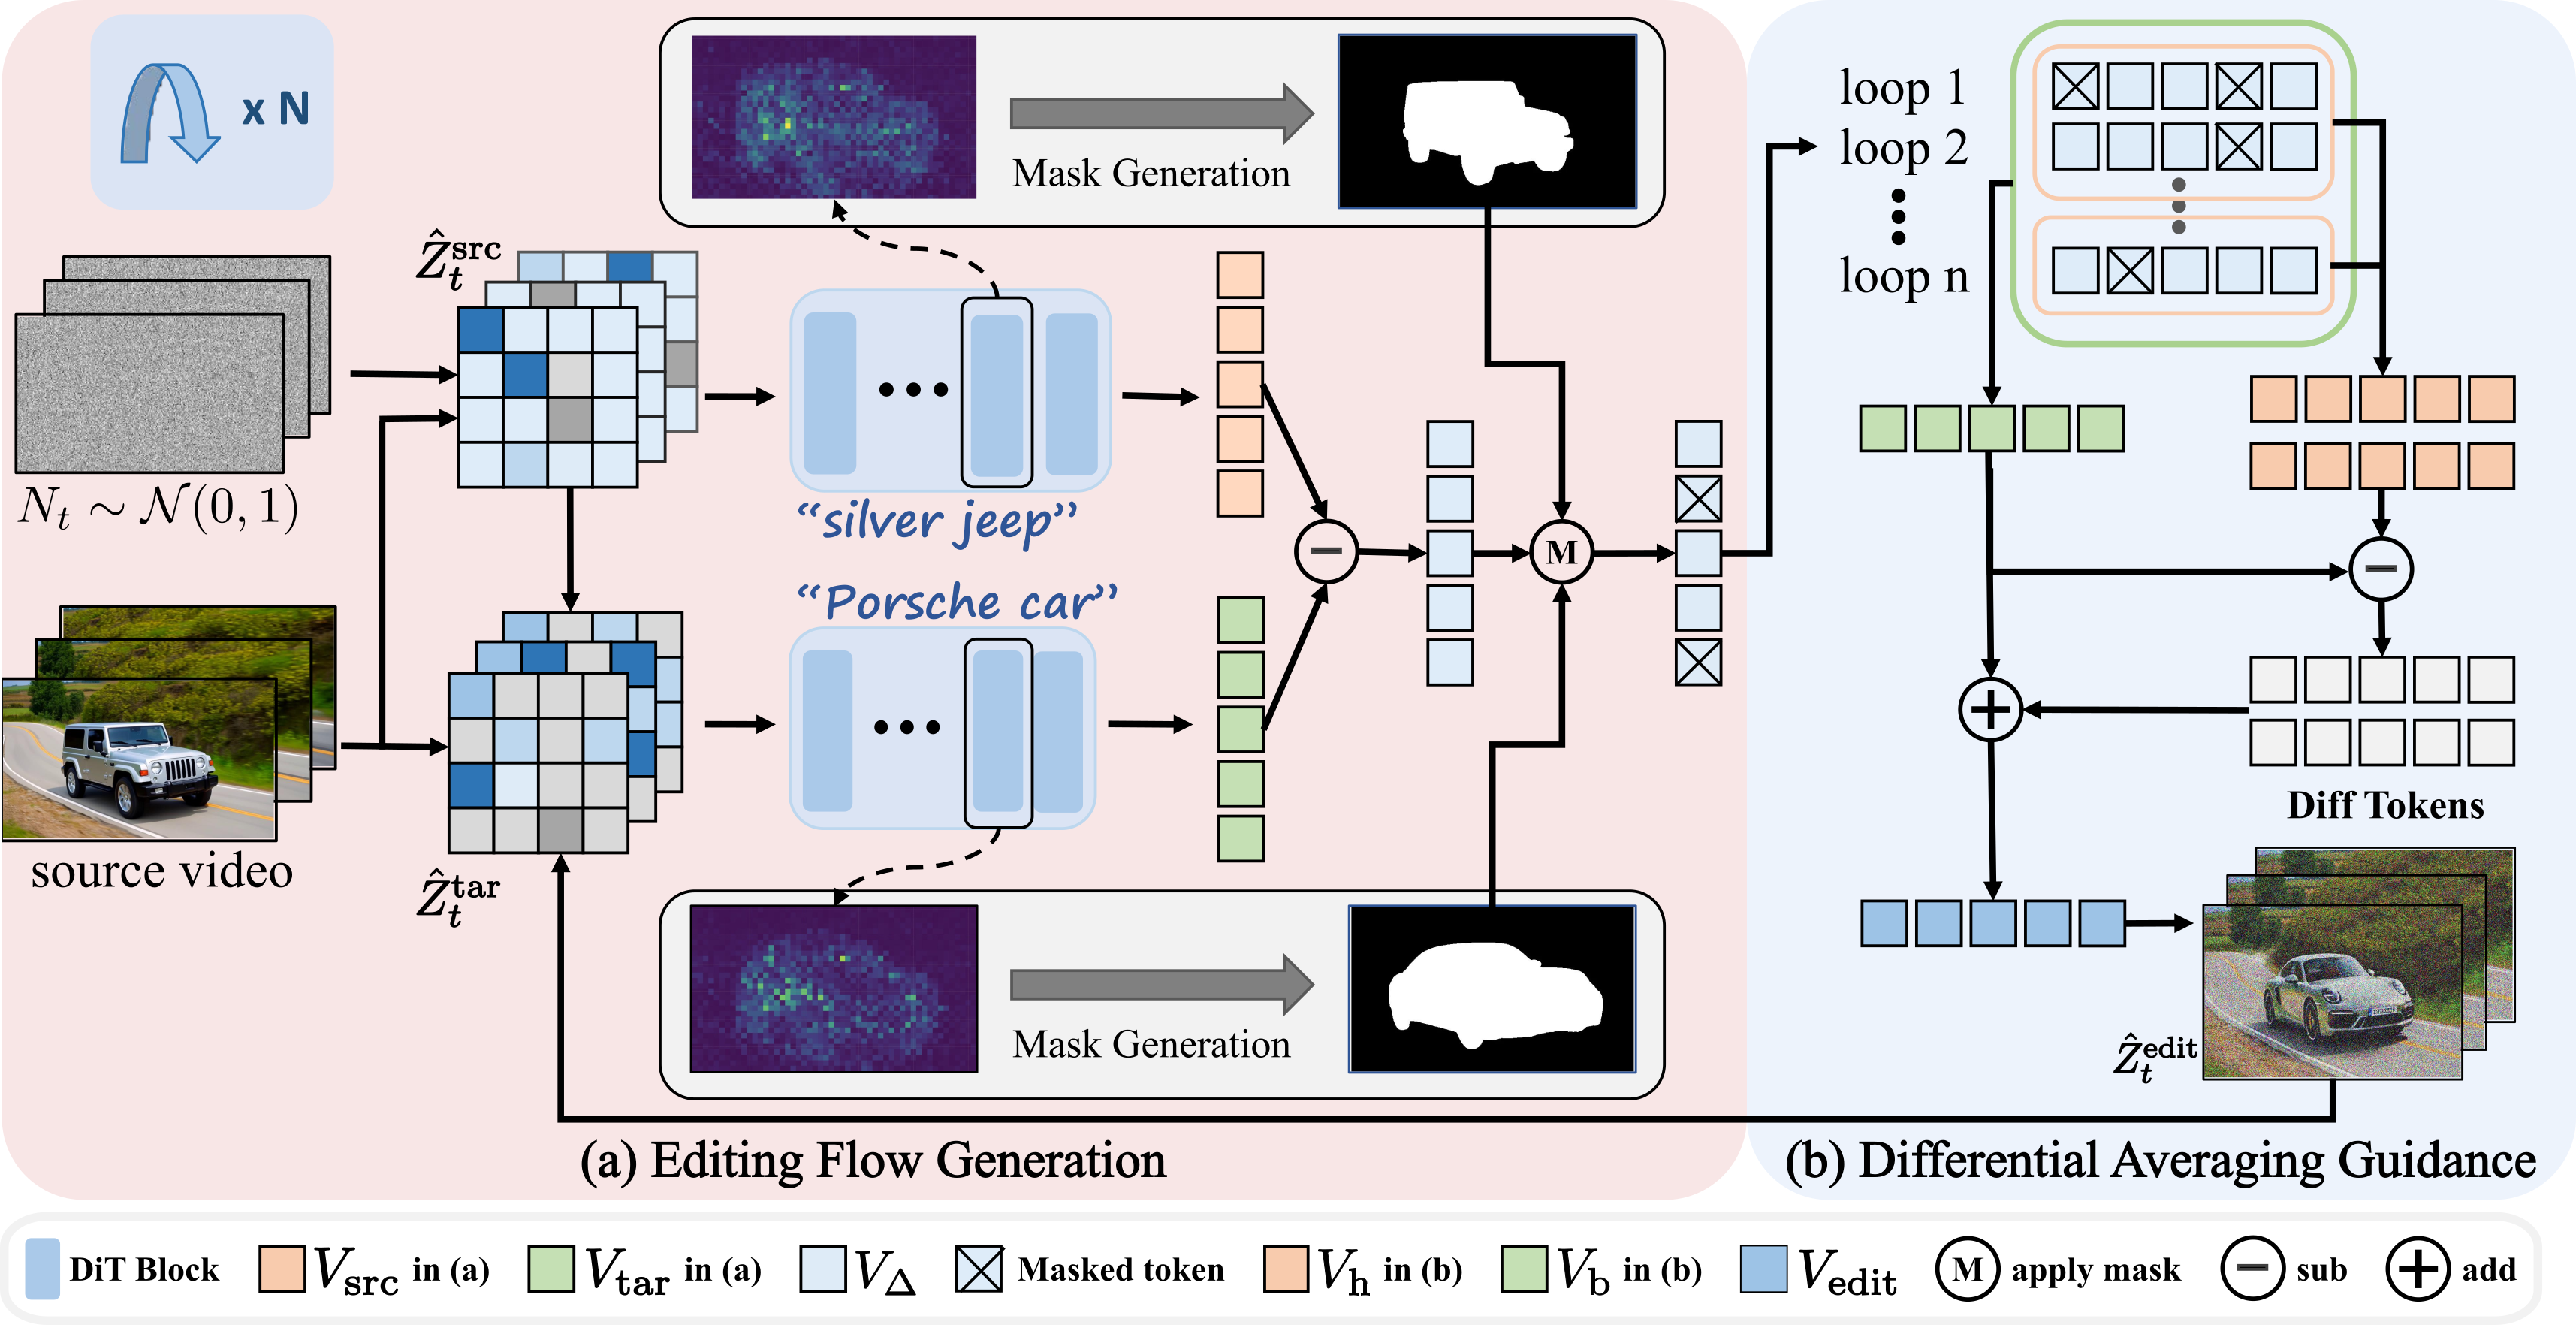
Edits videos through direct flow steering, without training or inversion.
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) 2026

Uses video scene graphs to enrich action recognition with structured context.
IEEE Transactions on Circuits and Systems for Video Technology (TCSVT)
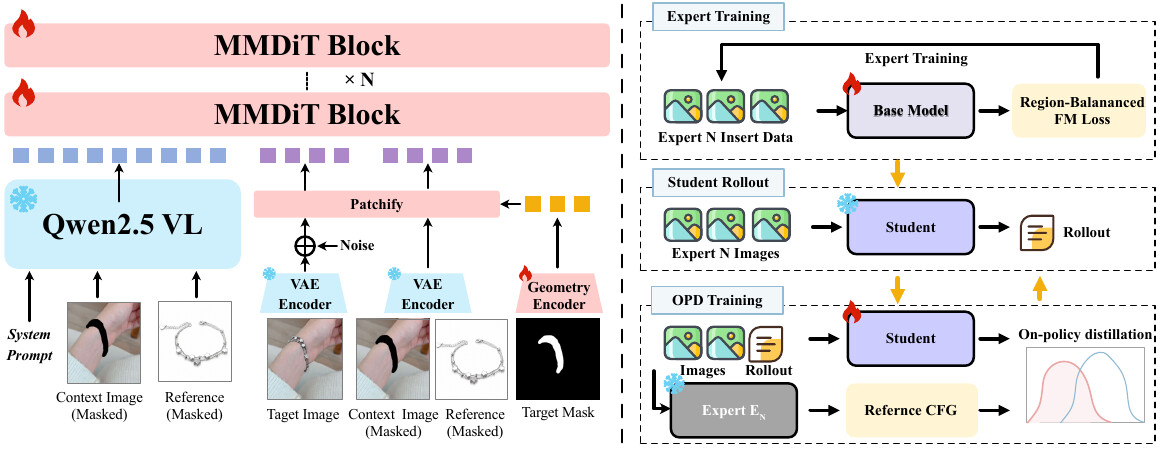
Distills category-specific insertion experts into one model with spatial guidance.
arXiv:2608.06490
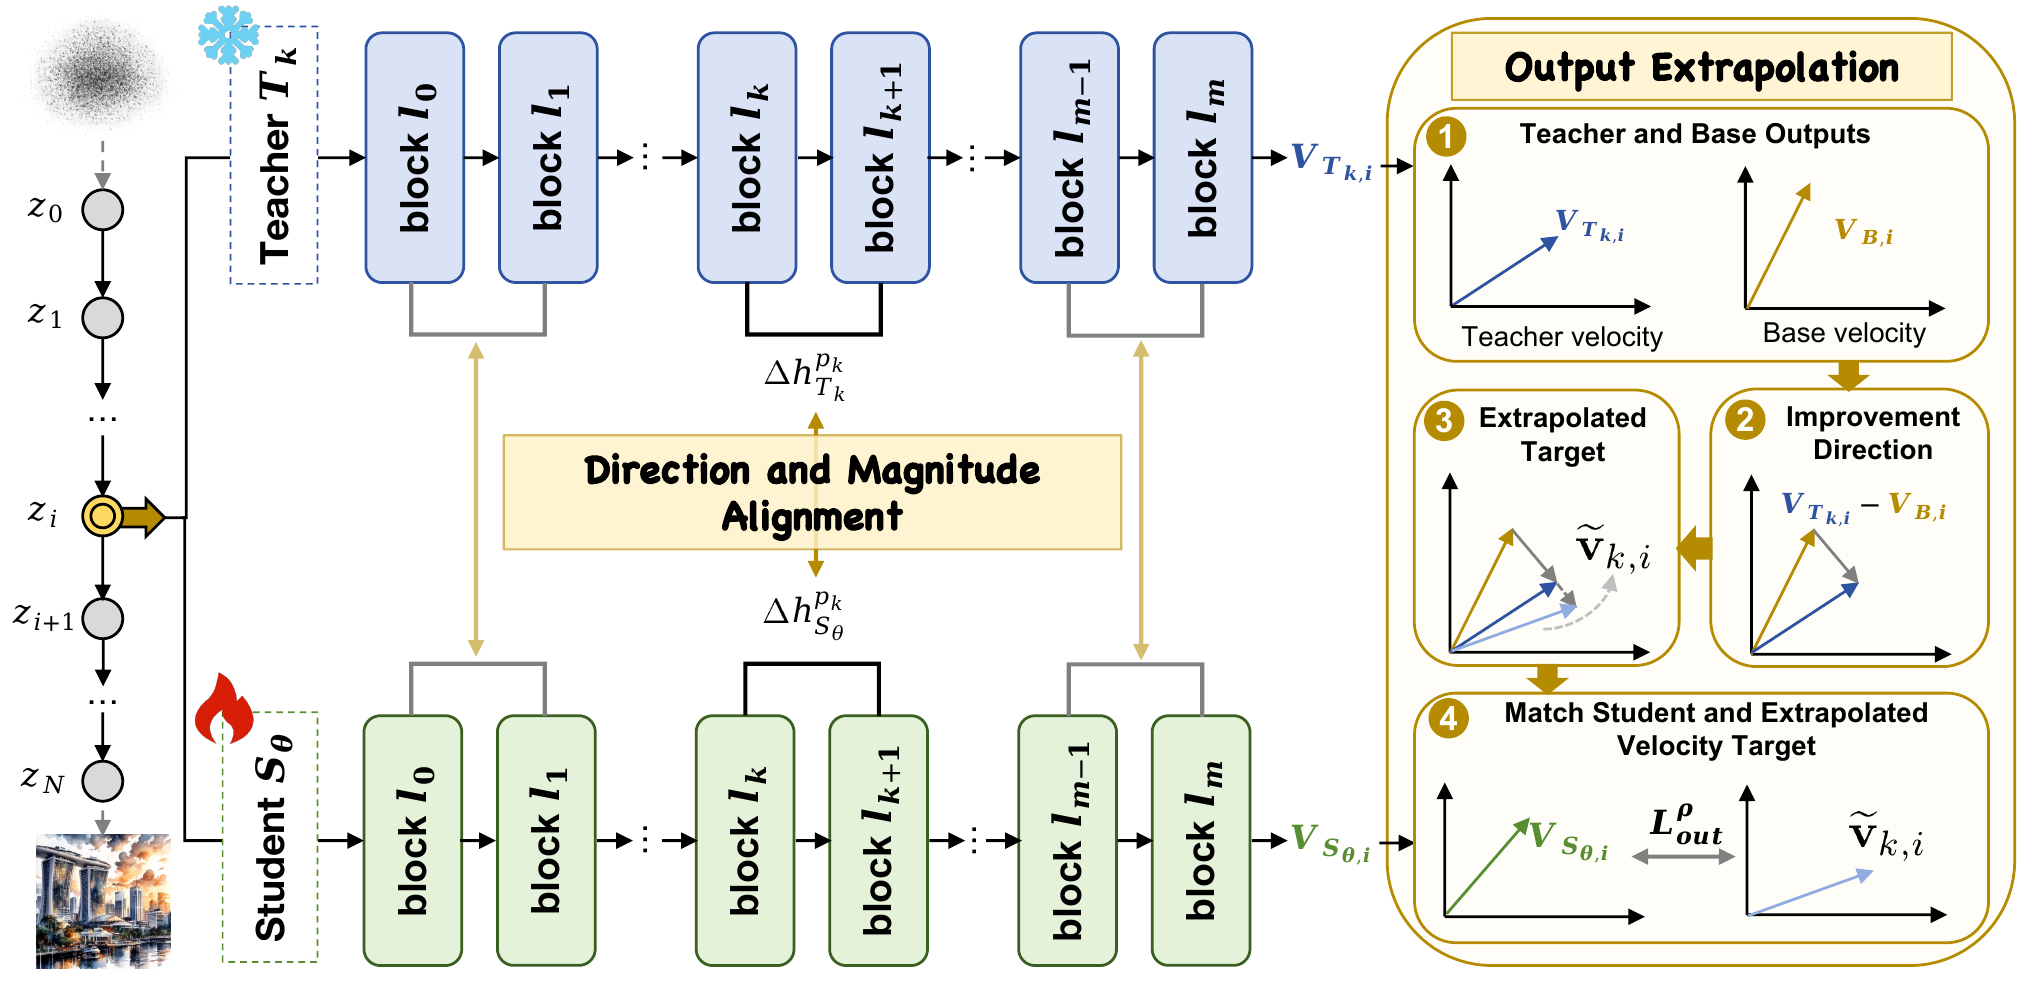
Combines beyond-teacher output targets with alignment of internal representation changes.
arXiv:2608.04887
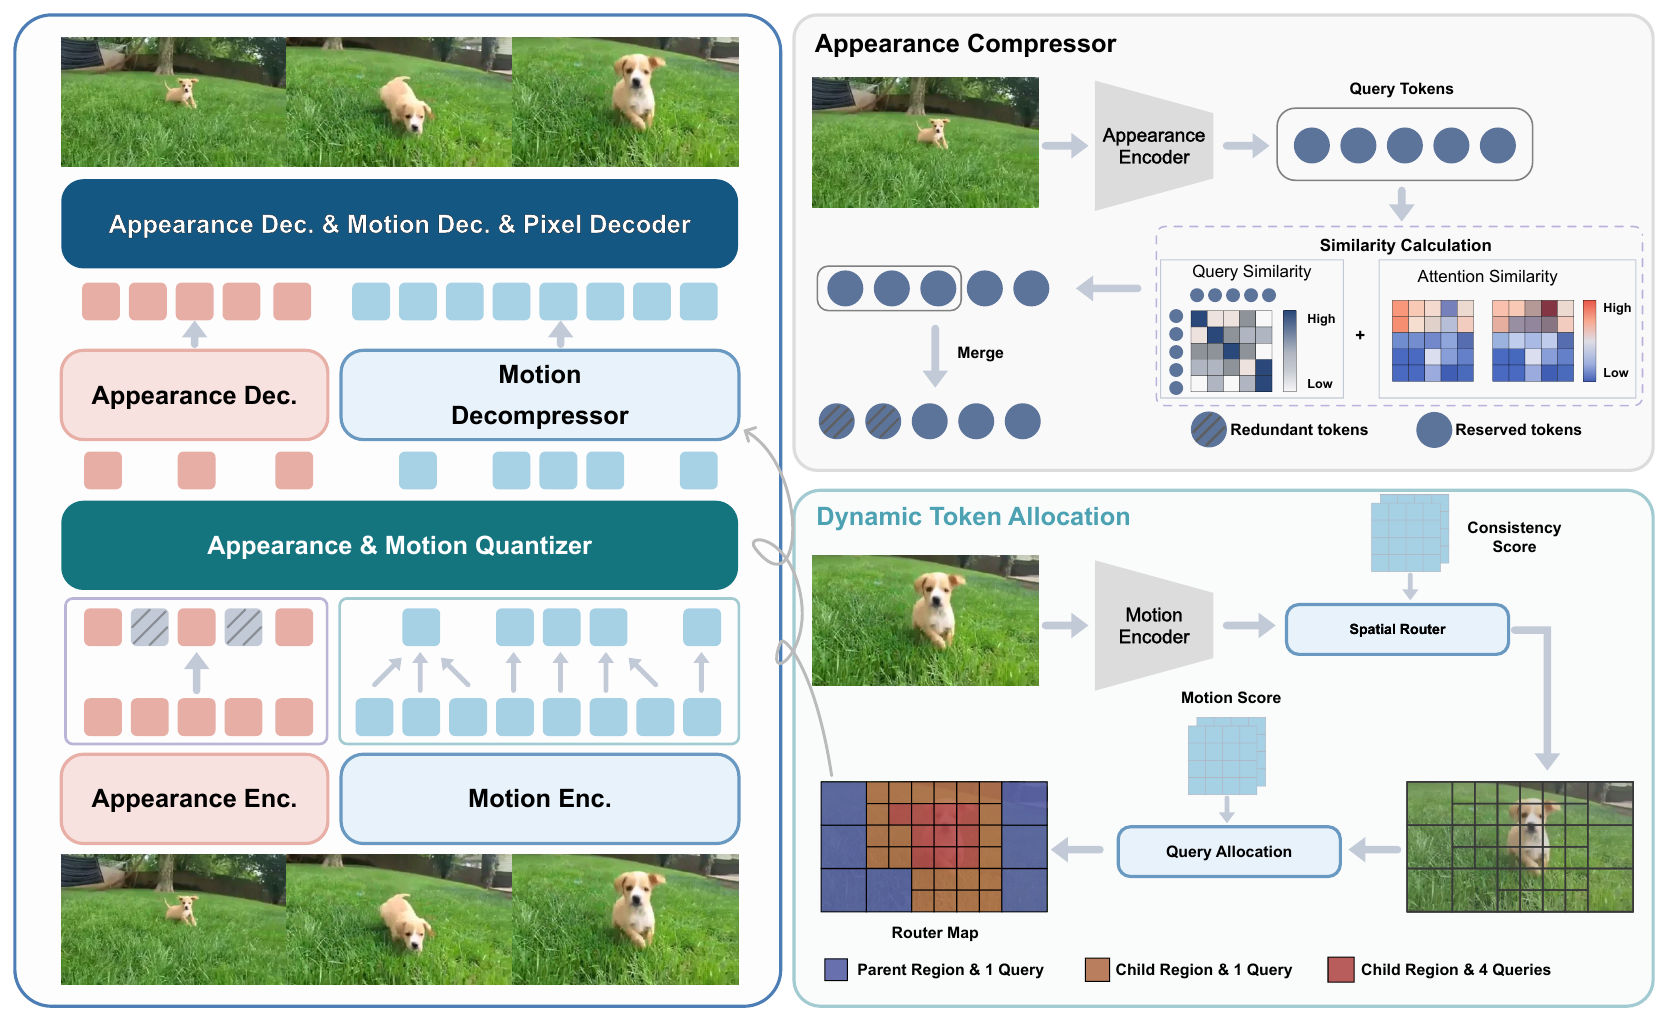
Compresses appearance and motion separately, allocating tokens according to video complexity.
Preprint coming soon
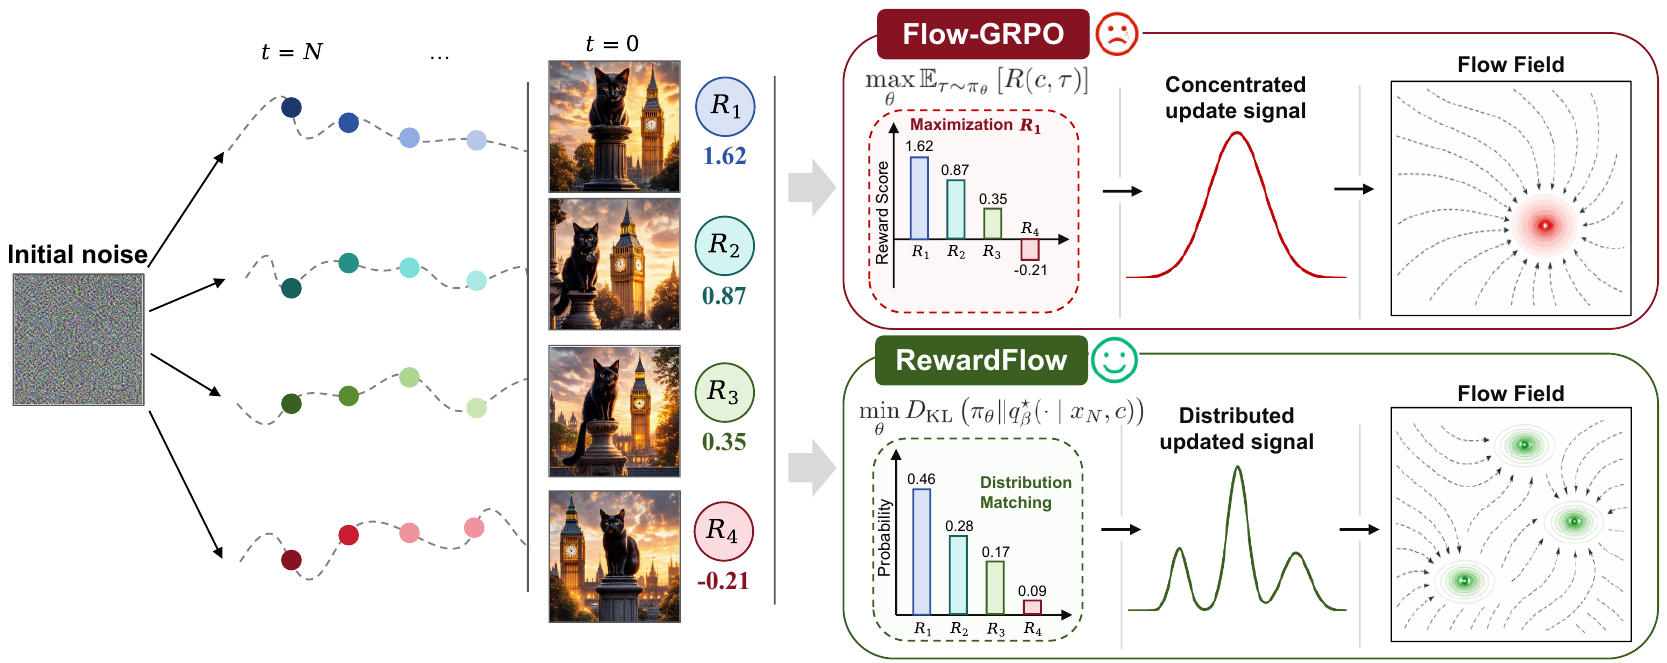
Matches reward distributions to retain multiple preferred generation trajectories.
Preprint coming soon